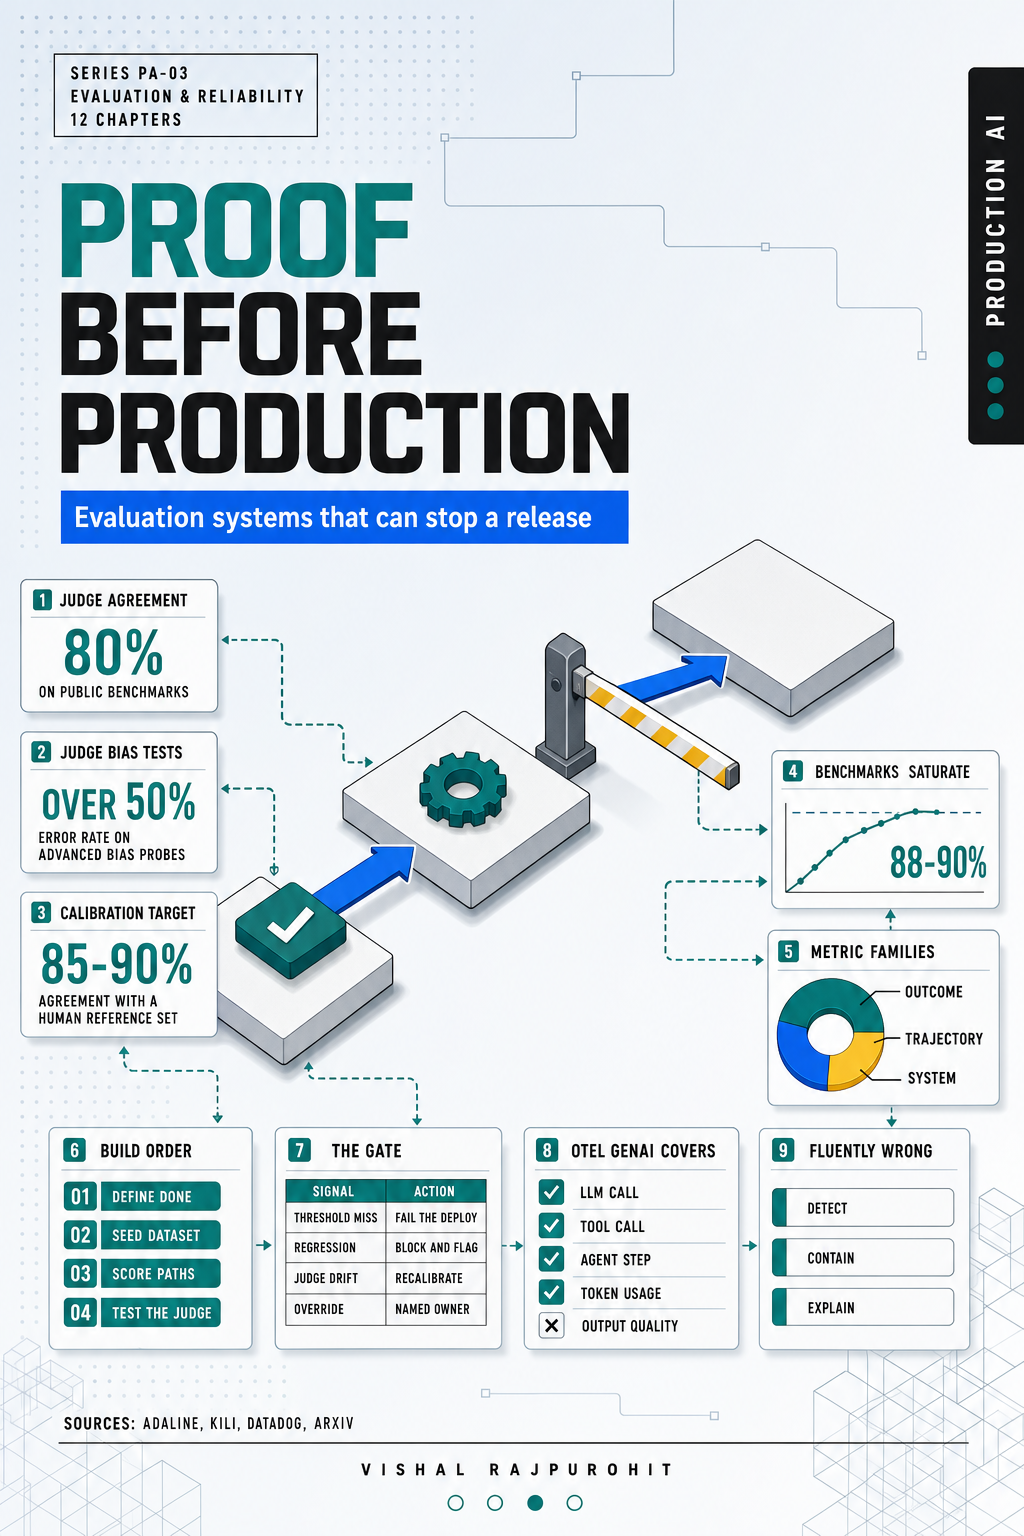
Proof Before Production
Evaluation systems that can stop a release
A probabilistic system cannot be shipped on taste, so evaluation has to be built like a build system: versioned datasets, trajectory scoring, judges you have tested, and gates wired into CI.
The demo passes because someone chose the inputs. The product fails quietly because production did not. This book builds the apparatus that closes the gap: a definition of done for open-ended output, a first dataset drawn from real traffic, metrics separated into outcome, trajectory and system, a judge calibrated against human annotation that carries its own error bar, and a suite with the authority to fail a deploy. It also draws the line where the OpenTelemetry GenAI conventions stop and your own evaluation data has to start.
What it makes operable
-
01
Define done for an open-ended output before writing a single eval
-
02
Build the first dataset out of real traffic and keep the seed set uncontaminated
-
03
Score trajectories, then calibrate the judge against a human-annotated reference set
-
04
Wire the suite into CI as a gate with the authority to fail a deploy
Contents
12 of 12 published
Every chapter is free to read in the browser, cites its own sources, and stands on its own if you came for one decision rather than the whole argument.
- 01 Why Demos Pass and Products Fail The distribution a demo samples, and the one production actually sends. 10 min
- 02 Defining Done for an Open-Ended Output Turning "a good answer" into criteria two reviewers would agree on. 10 min
- 03 Building the First Dataset From Real Traffic Sampling, labelling and splitting a seed set you will not contaminate. 10 min
- 04 Outcome, Trajectory, and System Metrics Three families of measurement, and what each one cannot tell you. 10 min
- 05 Scoring the Path, Not Just the Answer Path-invariant assertions for runs that legitimately take different routes. 10 min
- 06 LLM Judges Need Their Own Test Sets The judge as a system under test, against a human-annotated reference set. 10 min
- 07 Calibration, Bias, and Disagreement With Humans Chance-corrected agreement, bias probes, and a published error bar per score. 10 min
- 08 Benchmarks Saturate; Your Suite Should Not Why public scores stopped discriminating, and what to grow in their place. 10 min
- 09 Wiring Evals Into CI as a Release Gate Thresholds, regression rules, and who is allowed to override a red run. 10 min
- 10 Online Evaluation and Guarded Rollouts Shadow traffic, canaries, and the signal that triggers a rollback. 10 min
- 11 Tracing With OpenTelemetry GenAI Conventions The span hierarchy the conventions define, and where they deliberately stop. 10 min
- 12 Incident Response for Systems That Are Fluently Wrong Detecting, containing and explaining an error that reads as confident. 10 min
Evidence · 4 sources
Third-party sources behind the book's premise. Every figure in them belongs to the party that published it and is attributed to them in the text.